Is GPT Image 2.5 Sunburst Better Than GPT Image 2? A 48-Scene Blind Test

In a blind test of 48 commercial scenes, GPT Image 2.5 Sunburst clearly beats Qwen Image 2. Against GPT Image 2 it takes 52.7% of believability votes, which is not a clear win.
Evaluation period: 22–29 September 2026
Session: 1acf5c71-6445-4a84-9041-636e63e0fd80
Confidence: Directional
Corpus: anchor ladder v3, 48 scenes across 8 categories
In a blind test of 48 commercial scenes, Everypixel's production team preferred GPT Image 2.5 Sunburst over Qwen Image 2 on believability in 69.0% of votes, with a 95% interval of 63.4–74.6%. Against GPT Image 2 the share was 52.7%, with a 95% interval of 46.9–58.2% that includes a tie. The new model is a clear step above Qwen Image 2 and, on believability, not yet distinguishable from GPT Image 2 (Everypixel production team, September 2026).
GPT Image 2.5 Sunburst is OpenAI's flagship image generation and editing model, released in September 2026 alongside a faster sibling, GPT Image 2.5 Flare. OpenAI's image generation guide says: "Choose Sunburst for workflows where editing precision matters most, and Flare for fast, high-quality everyday image generation." We tested Sunburst on generation only.
The anchor ladder makes the question concrete. Qwen Image 2 and GPT Image 2 are fixed rungs with frozen strengths, so a new model gets a position against the same reference images every earlier model met. Sunburst clears the middle rung easily. At the top rung, the result is close enough that this panel cannot separate the two models on believability.
How we tested GPT Image 2.5 Sunburst
- Model under test: GPT Image 2.5 Sunburst through the Wavespeed endpoint, 2k resolution, quality set to high. Images came back at 2048 px on the long side. OpenAI's API also offers xhigh and max quality settings for this model, which we did not test.
- Anchors: Qwen Image 2, the middle rung of the ladder, and GPT Image 2, the strong rung. Their strengths were measured and frozen in our blind test of GPT Image 2 vs real photography. This run only fits the new model's position against them.
- Scenes: the ladder's 48 prompts, six in each of eight categories. Each prompt describes a reference photograph and asks for a photorealistic commercial image.
- Generations: three per scene, 144 in total. The endpoint did not accept a seed, so the exact frames cannot be regenerated from the prompts alone.
- Pairs: each generation was paired once with the Qwen Image 2 image and once with the GPT Image 2 image for the same scene, giving 288 blind pairs. Each anchor contributes one fixed image per scene, so all three Sunburst generations meet the same anchor image.
- Raters: 13 members of the Everypixel production team, three per pair. All 864 assigned judgments were submitted.
- Questions: three separate choices per pair, with a tie allowed: which image is more believable as a real photograph, which follows the prompt better, and which looks better.
- Missing answers: two answers are missing, one on prompt adherence and one on believability. The believability analysis therefore uses 863 votes, and one pair has two believability answers instead of three.
- Scoring: win share counts a tie as half a win, with the numerator always on GPT Image 2.5 Sunburst. Wins, ties and losses are also shown separately. Believability intervals come from a Bradley–Terry model with scene-clustered resampling. Prompt adherence and aesthetics intervals come from a bootstrap over scenes, 2,000 resamples.
- Agreement: Gwet's AC1 per scale over the three-way choice. We use AC1 rather than Fleiss' kappa because kappa drops toward zero when one answer dominates, as ties do on prompt adherence here, even when raters largely agree.
- What this method does not measure: positions above the top of the scale. The ladder saturates at the photographic anchor, fixed at 100, so a model whose interval runs past it gets a ceiling status instead of an index, as GPT Image 2.5 Sunburst does here.
Two limits apply to every number below. Raters agree weakly on individual pairs, so conclusions hold for the corpus and not for any single scene. The anchors are single frozen images, so this compares Sunburst outputs with those anchor outputs rather than with everything Qwen Image 2 or GPT Image 2 can produce.
GPT Image 2.5 Sunburst vs Qwen Image 2 vs GPT Image 2: results
| Scale | vs Qwen Image 2 | vs GPT Image 2 | Ties, vs GPT Image 2 | Gwet's AC1, vs GPT Image 2 |
|---|---|---|---|---|
| Believability | 69.0% (63.4–74.6%) | 52.7% (46.9–58.2%) | 33.4% | 0.08 |
| Prompt adherence | 64.6% (59.7–69.2%) | 55.2% (51.2–59.6%) | 60.0% | 0.34 |
| Aesthetics | 72.2% (67.4–77.1%) | 56.7% (50.7–63.1%) | 27.3% | 0.16 |
Against Qwen Image 2 every interval sits well above 50%. Against GPT Image 2 the believability interval includes 50%, and the other two lower bounds sit just above it.
GPT Image 2.5 Sunburst findings: believability, prompt adherence, aesthetics
Is GPT Image 2.5 Sunburst more realistic than Qwen Image 2?
Yes, by a wide margin and on every scale we measured.
Finding 1
GPT Image 2.5 Sunburst beats Qwen Image 2 on believability in 69.0% of 432 blind votes, with a Bradley–Terry probability of 68.9% (95% interval 63.4–74.6%). It also leads on prompt adherence (64.6%) and aesthetics (72.2%) (Everypixel production team, September 2026).
The widest gap is in layout and typography. Against Qwen Image 2, Sunburst won 47 of 54 believability votes in that category, tied 7 and lost none.
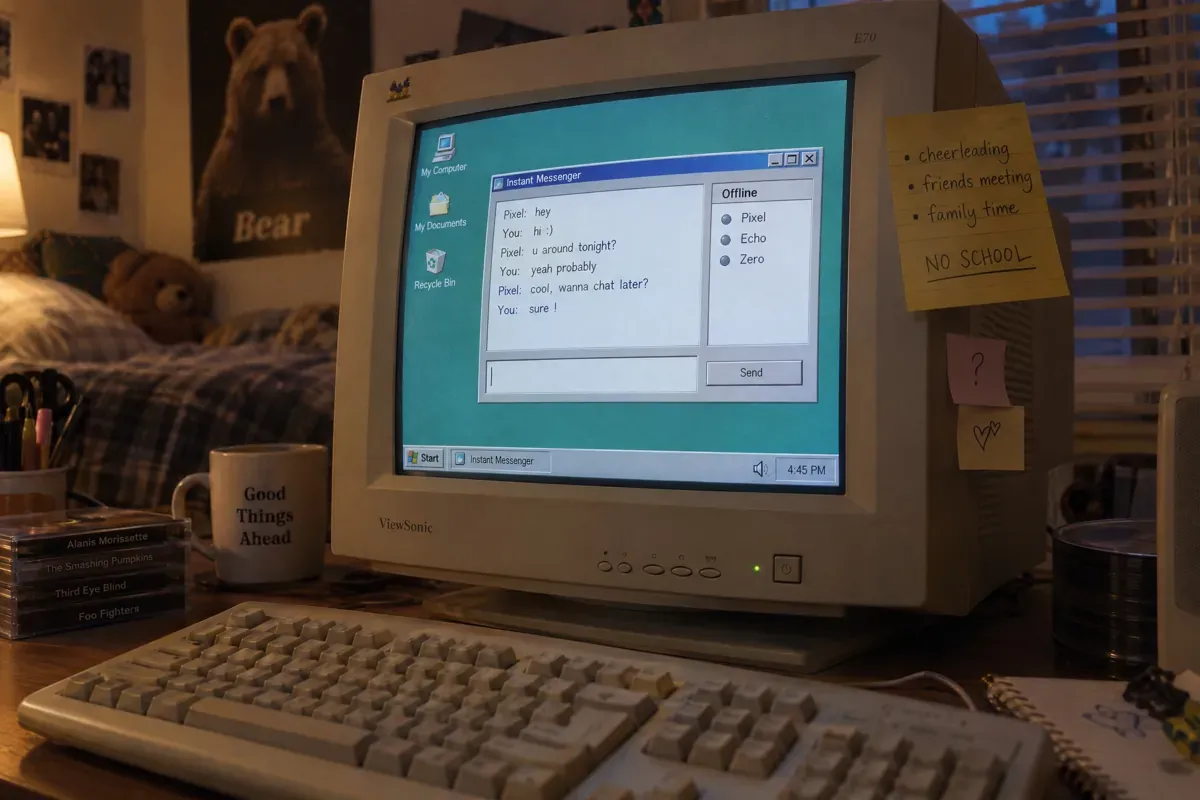
GPT Image 2.5 Sunburst
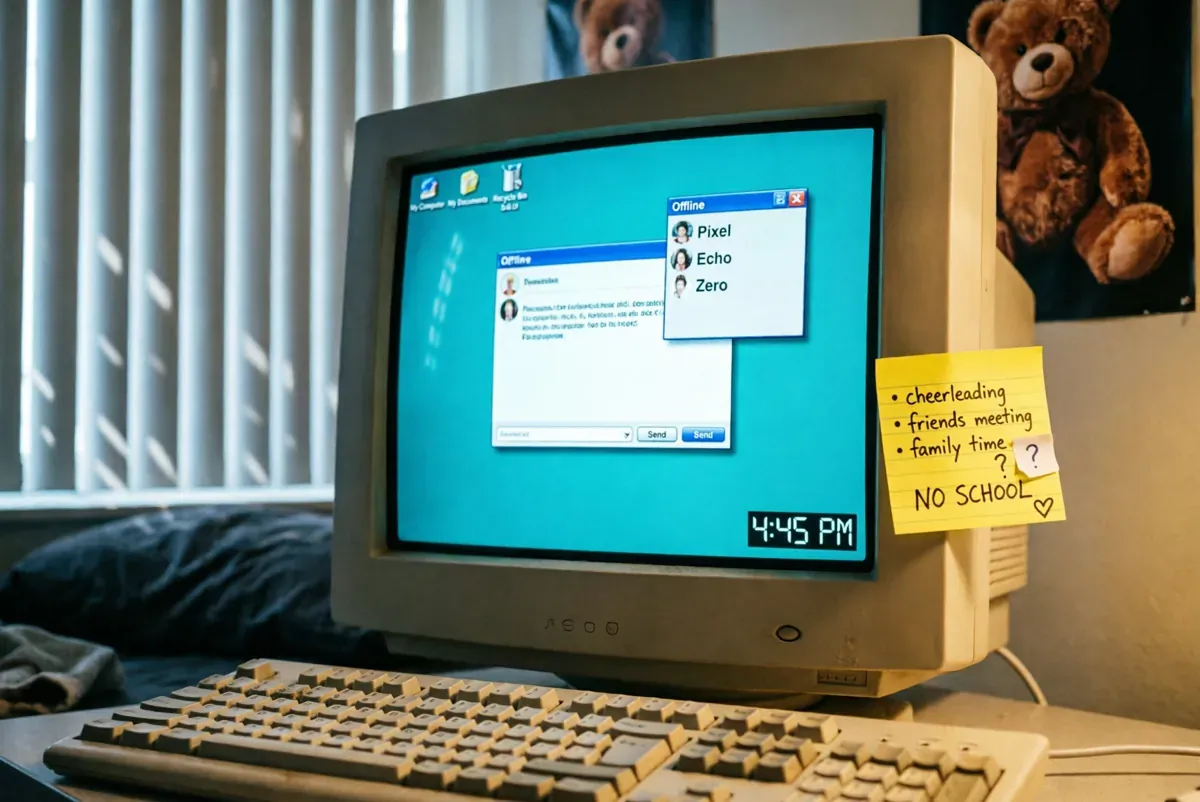
Qwen Image 2
layout_typography_04Is GPT Image 2.5 Sunburst better than GPT Image 2?
On believability, this study cannot tell them apart.
Finding 2
On believability, GPT Image 2.5 Sunburst wins 52.7% of 431 blind votes against GPT Image 2. The Bradley–Terry interval of 46.9–58.2% includes 50%, so the study does not establish that either model looks more like a real photograph (Everypixel production team, September 2026).
Rater agreement on this comparison is the lowest in the study. Gwet's AC1 is 0.08, which means the three raters on a pair often saw it differently. Treat the believability result against GPT Image 2 as a tie, not a narrow win.
Finding 3
Against GPT Image 2, GPT Image 2.5 Sunburst leans ahead on prompt adherence (55.2%, interval 51.2–59.6%) and aesthetics (56.7%, interval 50.7–63.1%). Both lower bounds sit just above 50%, so the advantage is directional and small (Everypixel production team, September 2026).
Prompt adherence was mostly a draw. Raters chose a tie in 60.0% of the GPT Image 2 pairs on that scale, which fits both models usually following the brief. When raters did pick a side, they picked Sunburst 109 times and GPT Image 2 64 times.
Agreement on aesthetics against GPT Image 2 is low, with Gwet's AC1 at 0.16. Read the aesthetics lead as a direction, not a settled result.
Do art directors agree with the overall result?
Not on believability. This is the strongest counter-argument to the headline, so it sits here rather than in a footnote.
Finding 4
In Everypixel's blind test, the four art directors on the panel gave GPT Image 2.5 Sunburst 47.7% of believability votes against GPT Image 2. Content distribution raters (54.2%) and quality assurance raters (55.6%) leaned the other way (Everypixel production team, September 2026).
The same pattern holds against Qwen Image 2. Art directors still preferred Sunburst, but by less: 60.5% on believability and 55.6% on aesthetics, compared with 80.8% and 85.3% from quality assurance. The role samples are small and descriptive, but they suggest the people closest to final visual sign-off are the least impressed.
Why does GPT Image 2.5 Sunburst have no ladder index?
Ladder index status: ceiling. The model sits at the top of the measurable scale, so no index is published.
Because its interval runs past the top of the scale. The ladder saturates where the photographic anchor is fixed at 100, so we report a ceiling status instead of a number.
Finding 5
We do not publish a believability index for GPT Image 2.5 Sunburst on Everypixel anchor ladder v3. Its 95% interval, 94–123, runs past the top of the scale, which saturates at the photographic anchor fixed at 100. The model sits at or above the measurable ceiling of the ladder: a ceiling status, not a score, and not evidence that its images are equivalent to real photographs (Everypixel production team, September 2026).
The head-to-head numbers remain the main result: GPT Image 2.5 Sunburst takes 69.0% of believability votes against Qwen Image 2 and 52.7% against GPT Image 2, with a tie counted as half a win.
No equivalence margin against photography was set before the run, so we make no such claim. The original ladder study already found the top of the scale hard to calibrate: GPT Image 2 ranked above the photographic reference in the full comparison network but not in direct comparison. A model that moves only slightly past GPT Image 2 lands in that same unresolved zone.
GPT Image 2.5 Sunburst by category (directional)
Sunburst falls behind GPT Image 2 in street and architecture scenes, and in fashion and beauty.
| Category | Share vs Qwen Image 2 | Share vs GPT Image 2 | Wins / ties / losses vs GPT Image 2 |
|---|---|---|---|
| Layout and typography | 93.5% | 61.1% | 22 / 22 / 10 |
| Interior | 64.8% | 58.3% | 24 / 15 / 15 |
| People and lifestyle | 75.0% | 55.6% | 23 / 14 / 17 |
| Social marketing | 64.8% | 55.6% | 21 / 18 / 15 |
| Food and beverage | 77.8% | 53.8% | 21 / 15 / 17 |
| Product and e-commerce | 66.7% | 51.9% | 20 / 16 / 18 |
| Fashion and beauty | 57.4% | 44.4% | 9 / 30 / 15 |
| Street and architecture | 51.9% | 40.7% | 15 / 14 / 25 |
Finding 6
GPT Image 2.5 Sunburst falls below an even split against GPT Image 2 on believability in two of eight categories: street and architecture (40.7%) and fashion and beauty (44.4%). Its strongest category against both anchors is layout and typography (Everypixel production team, September 2026).
Each category holds six scenes, so these rows show where to look next, not eight separate claims. Fashion and beauty is mostly ties: Sunburst won 9 of 54 votes there and tied 30. Street and architecture is also where its lead over Qwen Image 2 nearly disappears, at 51.9%.
Where GPT Image 2.5 Sunburst failed
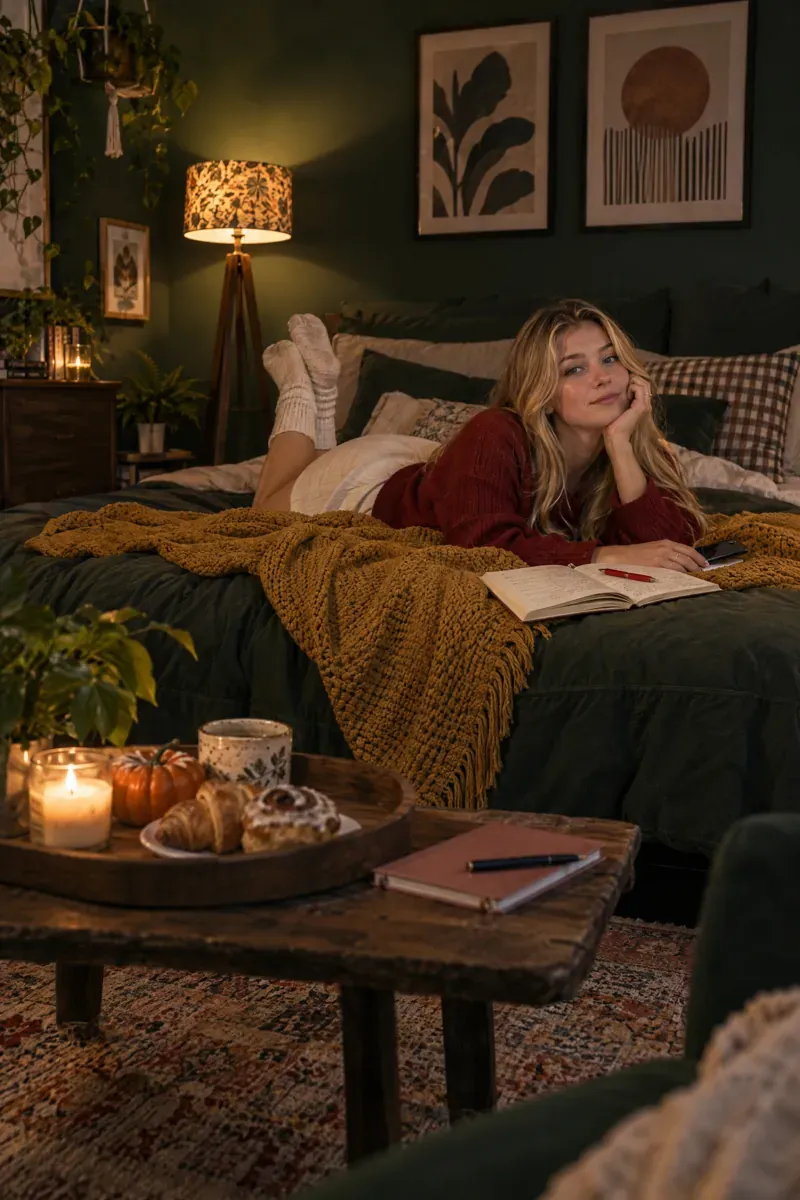
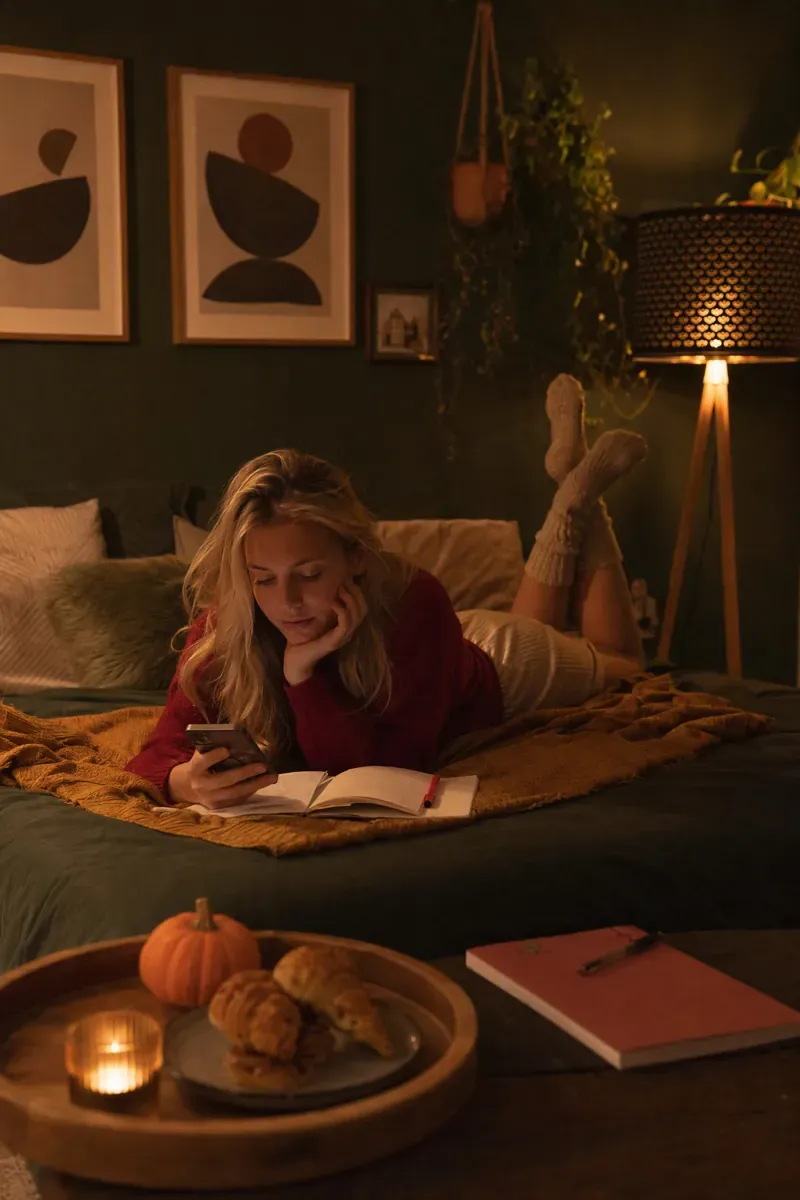
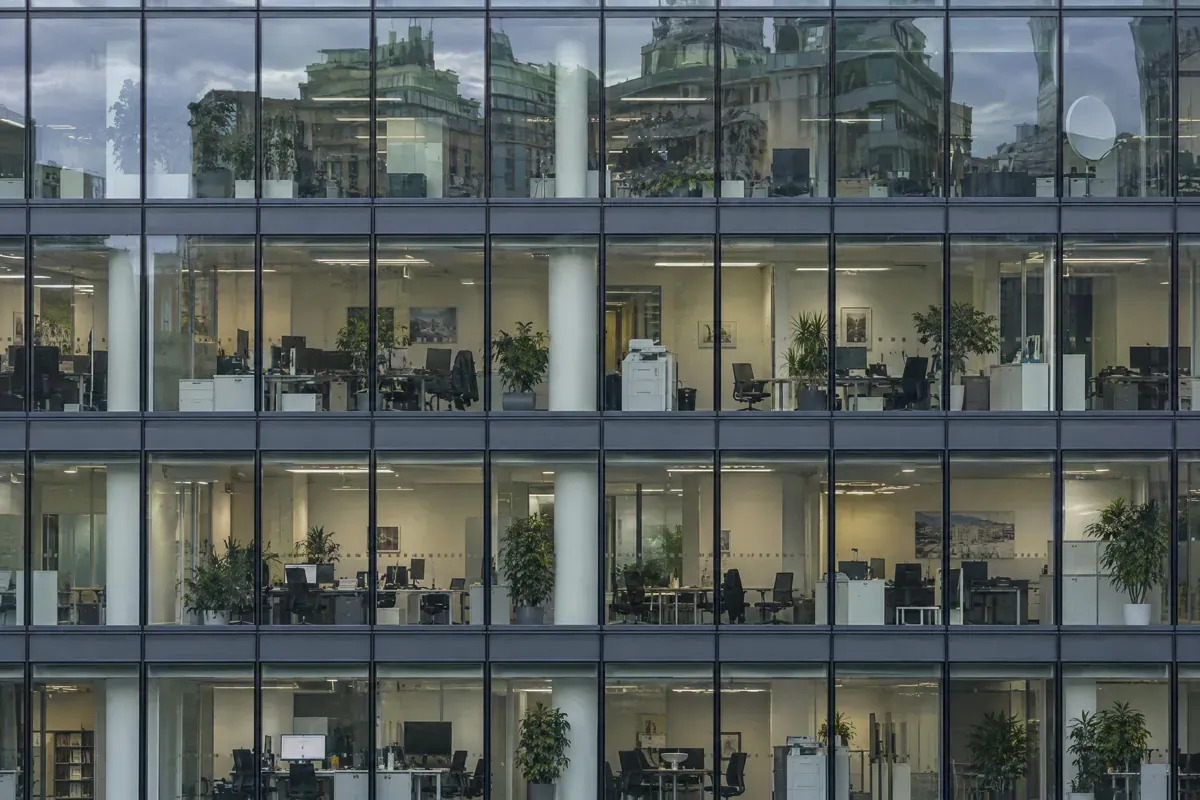
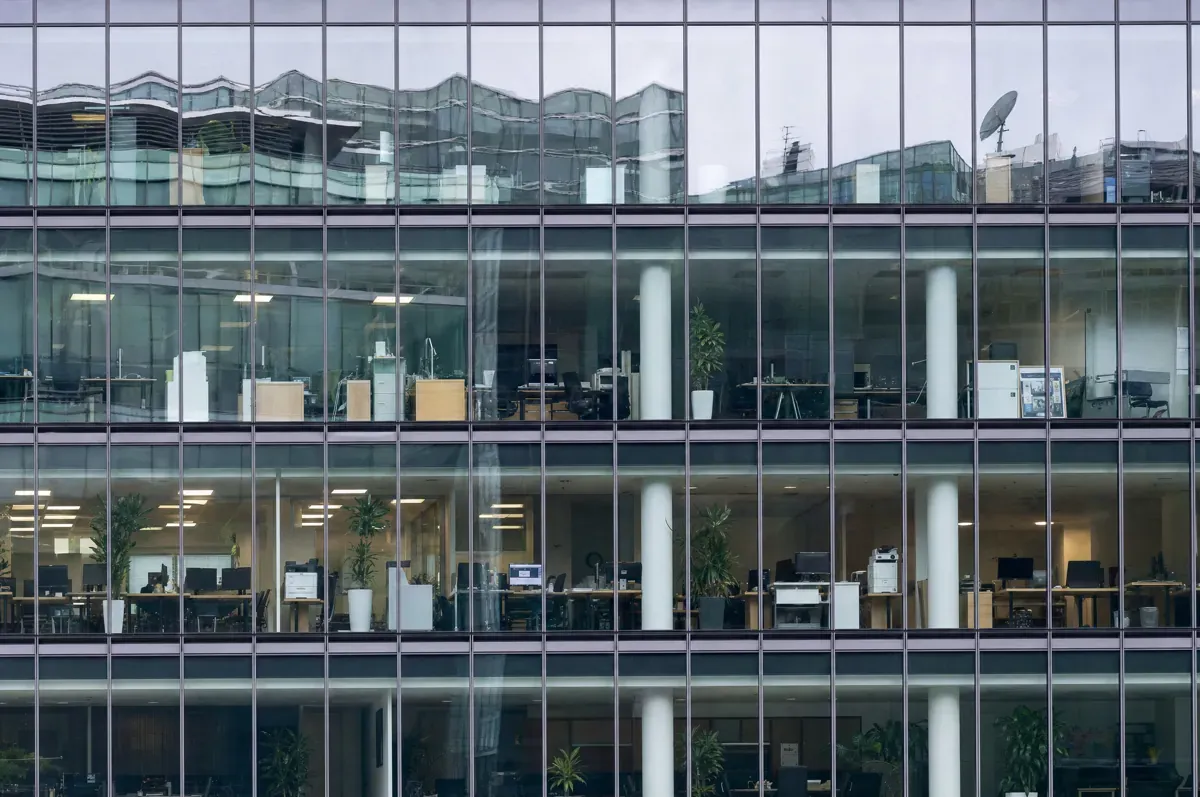
The clearest losses are a styled bedroom interior and a glass office facade. In both scenes GPT Image 2 took 7 of 9 believability judgments across the three Sunburst generations.
The bedroom scene asks for a woman lying across a bed in a dark green room, with a phone, a notebook, a red pen and knitted socks. Sunburst won none of the 9 judgments there, with 2 ties. Two of its three generations lost all three votes.
GPT Image 2.5 Sunburst
GPT Image 2
interior_05The facade scene is a flat telephoto view of a glass office tower, with lit offices visible through a grid of windows. Sunburst won 1 of 9 judgments and tied 1.
GPT Image 2.5 Sunburst
GPT Image 2
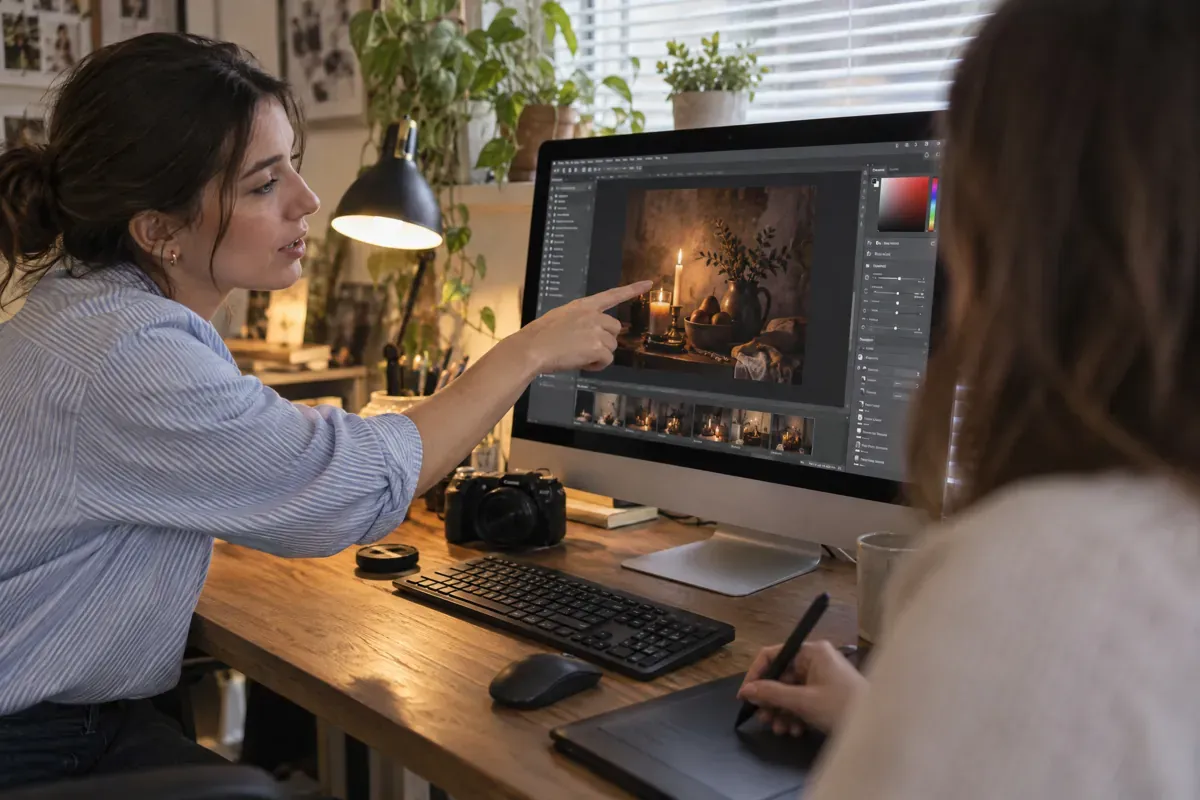
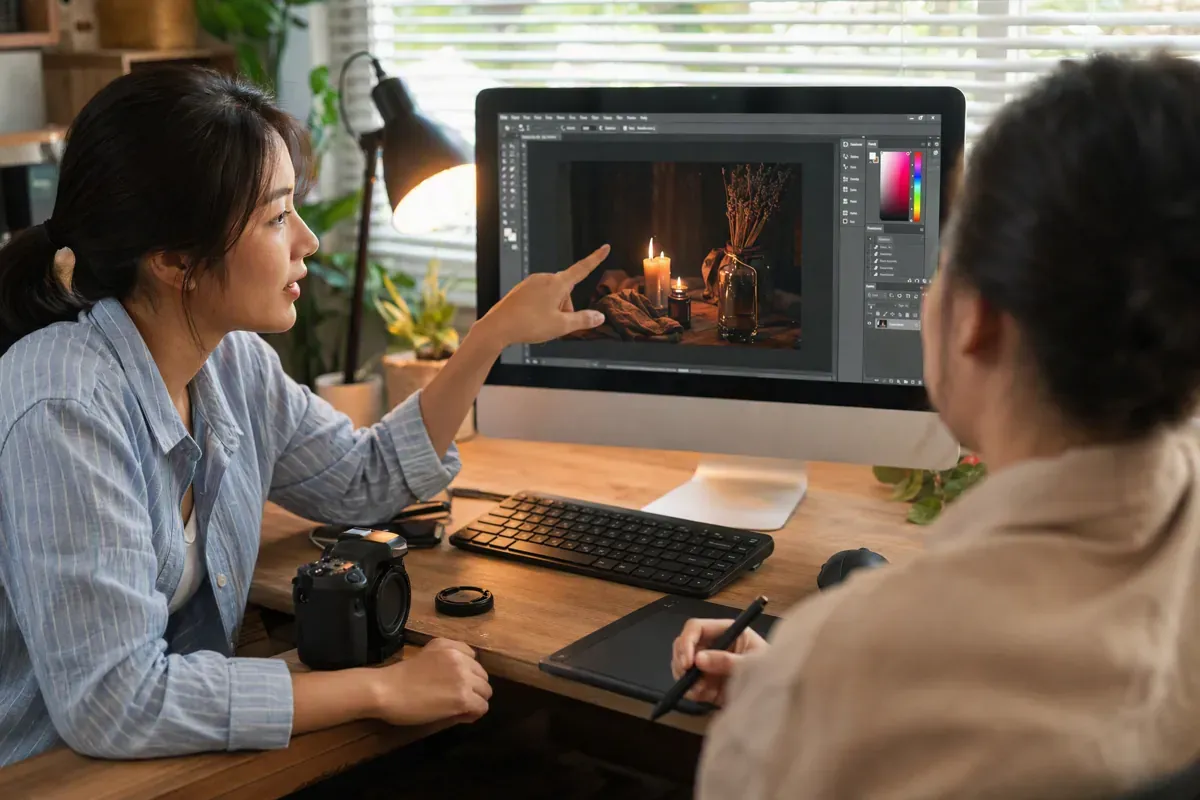
street_and_architecture_01The strongest win runs the other way. In a home office scene with two women at a monitor showing a photo-editing application, Sunburst won all 9 believability judgments against GPT Image 2.
GPT Image 2.5 Sunburst
GPT Image 2
people_and_lifestyle_05The case for GPT Image 2 against GPT Image 2.5 Sunburst
A defender of GPT Image 2 has a fair argument on believability. GPT Image 2 won or tied 64.0% of believability votes against Sunburst, and the interval on the head-to-head share includes an even split.
The specific evidence points the same way. GPT Image 2 holds the two categories where Sunburst falls below 50%, and the panel's art directors preferred GPT Image 2 on believability. GPT Image 2 is also the model Everypixel already offers, with known behavior across the earlier GPT Image 2.0 evaluation.
What a defender cannot claim is a lead on the other two scales. Sunburst's prompt adherence and aesthetics intervals both sit above 50%, even if only just.
What the results suggest for GPT Image 2.5 Sunburst tasks
| Task | Recommendation | Basis |
|---|---|---|
| Photoreal commercial images now made with Qwen Image 2 | Switch to Sunburst | 69.0% believability, 72.2% aesthetics vs Qwen Image 2 |
| Printed material, packaging text, layouts | Strong candidate | 93.5% vs Qwen Image 2, 61.1% vs GPT Image 2 on 6 scenes |
| Replacing GPT Image 2 for realism alone | No clear reason yet | 52.7% (46.9–58.2%) vs GPT Image 2 |
| Street and architecture | Keep GPT Image 2 or review outputs | 40.7% vs GPT Image 2 |
| Fashion and beauty close-ups | Keep GPT Image 2 or review outputs | 44.4% vs GPT Image 2, 9 wins of 54 |
| Fast drafts and many variants | Not tested; consider Flare | Median 51 s per image through Wavespeed |
| Editing existing images | Not tested | OpenAI positions Sunburst for editing precision |
Through Wavespeed, a single image took a median of 51 seconds wall-clock, ranging from 35 to 101 seconds across 144 generations. That suits final frames better than fast exploration.
What we did not test
- Editing. OpenAI positions Sunburst first for editing precision. This study covers generation only.
- Other modes and settings. GPT Image 2.5 Flare, the xhigh and max quality settings, other sizes, and other providers were not tested.
- Reproducibility. The Wavespeed endpoint did not accept a seed, so the same prompt will not return the same frames.
- Photographic equivalence. A ceiling status is a property of the scale, not a verdict against photography.
- Other content. All 48 scenes ask for a photorealistic commercial photograph. Illustration, stylized work and multi-image consistency were outside the scope.
- Outside raters. All 13 raters work at Everypixel. They did not know which model made which image.
GPT Image 2.5 Sunburst FAQ
Frequently asked questions
Is GPT Image 2.5 Sunburst better than GPT Image 2?
Not clearly. In Everypixel's blind test of 48 commercial scenes in September 2026, GPT Image 2.5 Sunburst won 52.7% of believability votes against GPT Image 2, with a 95% interval of 46.9–58.2% that includes a tie. It leaned ahead on prompt adherence (55.2%) and aesthetics (56.7%), but both advantages are small.
Is GPT Image 2.5 Sunburst better than Qwen Image 2?
Yes. Raters preferred it in 69.0% of believability votes, 64.6% of prompt adherence votes and 72.2% of aesthetics votes. The gap was widest in layout and typography, where it won 47 of 54 believability votes and lost none.
Are GPT Image 2.5 Sunburst images as good as real photographs?
This study does not show that. On the Everypixel anchor ladder its status is ceiling: the interval runs past the top of the scale, so no index is published. No equivalence test against photography was set up in advance.
Where is GPT Image 2.5 Sunburst weaker?
Against GPT Image 2, it scored below an even split on believability in street and architecture scenes (40.7%) and in fashion and beauty (44.4%). The art directors on the panel also gave it only 47.7% of believability votes against GPT Image 2.
What is the difference between GPT Image 2.5 Sunburst and Flare?
Both are OpenAI image generation and editing models released in September 2026. OpenAI recommends Sunburst for workflows where editing precision matters most and Flare for fast, high-quality everyday generation. Everypixel tested only Sunburst, on generation at high quality.
How long does GPT Image 2.5 Sunburst take to generate an image?
Through the Wavespeed API at 2k resolution and high quality, a single image took a median of 51 seconds wall-clock in September 2026, ranging from 35 to 101 seconds.
Can I check the data myself?
Yes. The anonymized votes, pair composition, prompts, generation metadata and results are available under CC BY 4.0. The 240 images shown to raters are supplied separately for verification.
About Everypixel and this test
Everypixel runs a platform where production teams generate, select and license AI visuals, and research.everypixel.com publishes the team's structured model evaluations. The raters are members of the Everypixel production team who work on stock, advertising and editorial content. Of the 48 reference photographs behind the ladder prompts, 38 come from Everypixel's own production and 10 from Unsplash.
Disclosure: Everypixel offers GPT Image 2 and Qwen Image 2.0, so Everypixel has a commercial interest in both model families. Everypixel does not offer GPT Image 2.5 Sunburst at the time of writing. If you are a vendor or reader and find an error, write to hello@everypixel.com.
Sources
- Image generation guide developers.openai.com/api/docs/guides/image-generation
External source accessed October 2026. Internal benchmark data is listed under Data below.
Data
The tabular data is licensed CC BY 4.0. It contains anonymized answers for all three scales, pair composition, the 48 prompts, generation metadata, the numeric results and the two missing answers. The image archive holds the 144 generated images and the 96 anchor images shown to raters. All image rights are reserved, and it is supplied for verification only. The fixed reference scale is in the anchor ladder v3 data.
Cite as: Everypixel research (2026). GPT Image 2.5 Sunburst on anchor ladder v3 [Data set].
Cite this article
<blockquote cite="https://research.everypixel.com/gpt-image-2-5-sunburst-vs-gpt-image-2/"> <p>In a blind test of 48 commercial scenes, GPT Image 2.5 Sunburst clearly beats Qwen Image 2. Against GPT Image 2 it takes 52.7% of believability votes, which is not a clear win.</p> <footer>— <a href="https://research.everypixel.com/gpt-image-2-5-sunburst-vs-gpt-image-2/">Is GPT Image 2.5 Sunburst Better Than GPT Image 2? A 48-Scene Blind Test</a>, Everypixel Research, October 2026</footer> </blockquote>
Everypixel Research. (2026). Is GPT Image 2.5 Sunburst Better Than GPT Image 2? A 48-Scene Blind Test. research.everypixel.com. https://research.everypixel.com/gpt-image-2-5-sunburst-vs-gpt-image-2/