Qwen Image 2.0 Pro vs Qwen Image 2: How Much Better Is Pro? A 48-Scene Blind Test

Qwen Image 2.0 Pro wins 47.0% of blind believability judgments against its predecessor (24.8% losses) and 19.7% against GPT Image 2 (50.6% losses).
Evaluation period: 11–22 September 2026
Session: a767ce6b-cf58-48eb-ac2f-7bbf6bb6f6ba
Confidence: Directional; ladder index provisional, not published as a finding
Corpus: anchor ladder v3, 48 scenes across 8 categories
Update, 29 September 2026. An earlier version of this article reported a ladder index of 80 (95% CI 69–94) as a finding. That interval is wider than our publication threshold allows, so the index is now shown as provisional while more votes are collected. All head-to-head results are unchanged.
Qwen Image 2.0 Pro is a real upgrade over Qwen Image 2 but does not reach GPT Image 2. In our 48-scene blind test, Pro won 47.0% [40.0, 53.9] of believability judgments against its predecessor, which won 24.8%. Against GPT Image 2 it reversed: 19.7% for Pro, 50.6% for GPT Image 2. Its position on our anchor ladder is not yet measured precisely enough to publish. Agreement was low, so the result is directional (Everypixel production team, September 2026).
Qwen Image 2.0 Pro vs Qwen Image 2 is an easy comparison to place on our anchor ladder, because the predecessor already defines the ladder's middle rung. The test shows how far the Pro version moves from that rung, and how much of the distance to GPT Image 2 it covers.
The upgrade shows on every scale: largest on attractiveness, smallest on prompt adherence. Its exact position on the ladder between the two anchors is not yet measured precisely enough to publish.
How we tested Qwen Image 2.0 Pro
- Model under test: Qwen Image 2.0 Pro through the WaveSpeed endpoint
alibaba/qwen-image-2-pro, 2048 px on the long edge, fixed seeds, three independent generations per scene, 144 generations in total. - Anchors: Qwen Image 2, the middle rung of the ladder, and GPT Image 2, the strong rung, with strengths frozen from the August baseline. The experiment package does not record their API endpoints or generation settings, as in the original ladder study.
- Scenes: the ladder's 48 prompts, 6 in each of 8 categories, with the same aspect ratios. Each prompt was written by describing a reference photograph.
- Generations per side: the Pro version contributes three generations per scene; each anchor contributes one fixed image per scene, frozen from the August study. Generation-to-generation variation is therefore measured for Pro and not for the anchors: if an anchor image happens to be weak or strong for its model, all three Pro generations meet that same image.
- Pairs: each generation was shown once against each anchor, 288 pairs in total. The model under test appeared on the left in 72 of the 144 pairs against each anchor.
- Raters: 13 professionals judging blind, three per pair except one pair seen by two, for 863 judgments per scale and 2,589 responses.
- Questions: three separate choices per pair, with "equal" allowed: which image follows the prompt better, which is more believable as a real photograph, which is more attractive.
- Scoring: Bradley–Terry strength per model with 95% intervals. Win, tie and loss shares are counted separately; a tie is never split into half a win. Intervals on win shares come from a bootstrap over scenes (2,000 resamples). They show how stable the result is across scenes with this panel of 13 evaluators, not a confidence interval over production professionals in general.
- Agreement: Gwet's AC1 per scale over the three-way choice. We use AC1 rather than Fleiss' kappa because kappa collapses toward zero when votes pile up on one option, which ties do here.
The anchor ladder is a set of fixed reference tiers with frozen strengths, so a new model gets a position on an absolute scale instead of a result that only holds against its current opponent. The scale uses believability, with the real photograph pinned at 100. Its design and its limits are in our blind test of GPT Image 2 vs real photography, which also explains why the photograph did not behave as a stable top anchor.
Three limits apply to every number below. Raters agree weakly on individual pairs, so conclusions hold for the corpus and not for any single scene. The anchors are single frozen images, so the comparison is between Pro outputs and those anchor outputs, not a full model-against-model test of Qwen Image 2 and GPT Image 2.
Why the ladder uses believability, not prompt adherence
The prompts were written from reference photographs. A generator can follow the written description exactly; the photograph cannot, because it carries detail the description never mentions. Prompt adherence is therefore not a neutral scale for a ladder anchored on a photograph, and the ladder index uses believability only.
Qwen Image 2.0 Pro vs Qwen Image 2 vs GPT Image 2: results
| What we measured | vs Qwen Image 2 | vs GPT Image 2 |
|---|---|---|
| Believability, strength gap (95% CI) | Pro ahead by +0.45 (+0.21 to +0.72) | GPT Image 2 ahead by +0.64 (+0.42 to +0.86) |
| Believability, Pro wins / ties / losses | 47.0% / 28.2% / 24.8% | 19.7% / 29.7% / 50.6% |
| Attractiveness, Pro wins / ties / losses | 63.0% / 15.5% / 21.5% | 26.0% / 19.5% / 54.5% |
| Prompt adherence, Pro wins / ties / losses | 27.5% / 54.4% / 18.1% | 13.7% / 57.1% / 29.2% |
| Weakest category for Pro, believability | Product and E-commerce: 33.3% wins, 29.6% losses | Fashion and beauty: 7.5% wins, 64.2% losses |
| Raters who favored Pro on believability | 11 of 13 | 0 of 13 |
| Anchor ladder index (believability, photograph = 100) | Not published: 95% CI half-width 12.5 points, above the 10-point limit | More votes are being collected |
| Rater agreement, Gwet's AC1 | Believability 0.18, attractiveness 0.24, prompt adherence 0.30 (whole session) | Same session |
The Pro version wins more than it loses against its predecessor on all three scales, and loses more than it wins against GPT Image 2 on all three.
Qwen Image 2.0 Pro findings: believability, attractiveness, prompt adherence
Is Qwen Image 2.0 Pro better than Qwen Image 2?
Finding 1
Qwen Image 2.0 Pro outputs were judged more believable as photographs than the frozen Qwen Image 2 anchor outputs in this corpus. The strength gap is +0.45 (95% CI +0.21 to +0.72), and the Pro version wins 47.0% of blind judgments (95% CI 40.0–53.9%) against 24.8% losses and 28.2% ties (Everypixel production team, September 2026).
The interval excludes zero, so the direction holds across the corpus. Its size is less certain: the interval runs from +0.21 to +0.72, and believability has the lowest rater agreement of the three scales (AC1 0.18).
Where does the upgrade show up most?
Finding 2
Attractiveness is where Qwen Image 2.0 Pro gains most over Qwen Image 2: it wins 63.0% of judgments (95% CI 56.7–69.4%) and loses 21.5%. The fitted strength gap is +0.88 on attractiveness, against +0.45 on believability and +0.19 on prompt adherence (Everypixel production team, September 2026).
All three rater roles agree on the direction. Production QA testers are the most convinced, at 74.4% wins for the Pro version on attractiveness; art directors are the least, at 57.1%.
A defender of Qwen Image 2 would say most of the upgrade sits on the most subjective scale, the one least tied to a brief. The data does not rule that reading out. The believability gain is smaller, but it is also clear of zero.
Does Qwen Image 2.0 Pro follow prompts better?
Finding 3
Prompt adherence barely separates Qwen Image 2.0 Pro from Qwen Image 2: 54.4% of judgments are ties, the Pro version wins 27.5% and loses 18.1% (Everypixel production team, September 2026).
Raters mostly saw both versions follow the brief equally well. Treat this scale as directional: it has the most ties and carries the prompt-construction bias described in the methodology.
Is Qwen Image 2.0 Pro as good as GPT Image 2?
Finding 4
GPT Image 2 stays ahead of Qwen Image 2.0 Pro on believability by +0.64 (95% CI +0.42 to +0.86), a wider margin than the Pro version's gain over its predecessor. Against GPT Image 2, Pro wins 19.7% of judgments (95% CI 15.2–24.4%) and loses 50.6% (Everypixel production team, September 2026).
GPT Image 2 also leads on attractiveness (54.5% against 26.0%) and on prompt adherence (29.2% against 13.7%, with 57.1% ties). All 13 raters gave GPT Image 2 more believability wins than the Pro version, and the lead holds in every role: art directors gave GPT Image 2 45.5% of believability judgments, distribution reviewers 49.4%, QA testers 57.1%.
GPT Image 2 was also scored on real production briefs in our GPT Image 2.0 review. That study used a different method, so its numbers do not combine with these.
Where does Qwen Image 2.0 Pro land on the anchor ladder?
Finding 5
Qwen Image 2.0 Pro's position on the Everypixel anchor ladder is not yet measured precisely enough to publish as a finding: its provisional 95% interval runs from 69 to 94 points, a half-width of 12.5 against the 10-point limit Everypixel sets for publishable scores (Everypixel production team, September 2026).
The provisional point estimate of 80 falls between Qwen Image 2 at 64.5 and GPT Image 2 at 104.4, which is where a working scale should place a model bracketed by those two rungs. We do not report it as a result, or derive a share of the gap from it, until the interval narrows. More votes are being collected, and this section will be updated with the new figure.
The head-to-head results in this article do not depend on the ladder index and are unchanged.
Does the upgrade hold across content categories?
Finding 6
The Pro upgrade is uneven by category. Its fitted gain over Qwen Image 2 is +0.98 in both People and Lifestyle and Layout & Typography, and close to zero in Product and E-commerce (+0.07) and Fashion and beauty (+0.11) (Everypixel production team, September 2026).
| Category | Fitted gain vs Qwen Image 2 | vs Qwen Image 2: wins / losses | vs GPT Image 2: wins / losses |
|---|---|---|---|
| People and Lifestyle | +0.98 | 57.4% / 11.1% | 29.6% / 59.3% |
| Layout & Typography | +0.98 | 59.3% / 13.0% | 16.7% / 59.3% |
| Interior | +0.60 | 51.9% / 22.2% | 22.2% / 40.7% |
| Food and Beverage | +0.44 | 51.9% / 29.6% | 16.7% / 51.9% |
| Social Marketing | +0.33 | 46.3% / 29.6% | 25.9% / 33.3% |
| Street and Architecture | +0.15 | 38.9% / 31.5% | 24.1% / 53.7% |
| Fashion and beauty | +0.11 | 37.0% / 31.5% | 7.5% / 64.2% |
| Product and E-commerce | +0.07 | 33.3% / 29.6% | 14.8% / 42.6% |
The two categories closest to catalog work, product and fashion, show the least improvement over the predecessor. Fashion and beauty is also where GPT Image 2 leads by the widest margin, with 64.2% of believability judgments against 7.5%.
Each category rests on 6 scenes and about 54 judgments per anchor, and the category gaps carry no intervals in this session. Read the ordering as a hypothesis for a larger run, not as a routing rule.
Where Qwen Image 2.0 Pro failed
Finding 7
One scene went against Qwen Image 2.0 Pro on believability with both anchors: an overhead shot of utility bills with dense small print and a red PAST DUE stamp. Across 18 judgments it won none, with 5 ties and 13 losses (Everypixel production team, September 2026).
Example images below are generation 1 of the three the Pro version produced per scene. We picked scenes where the vote went the same way across all of them; every image is in the archive under Data.
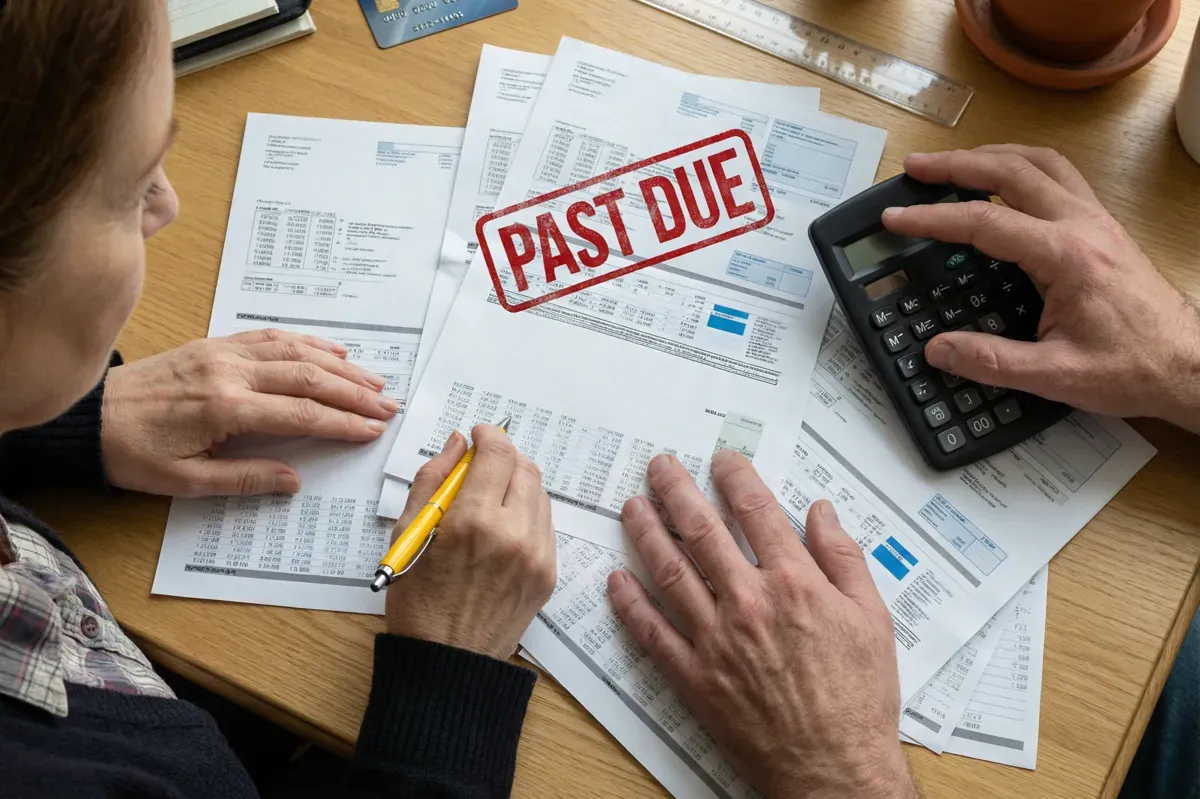
Qwen Image 2.0 Pro
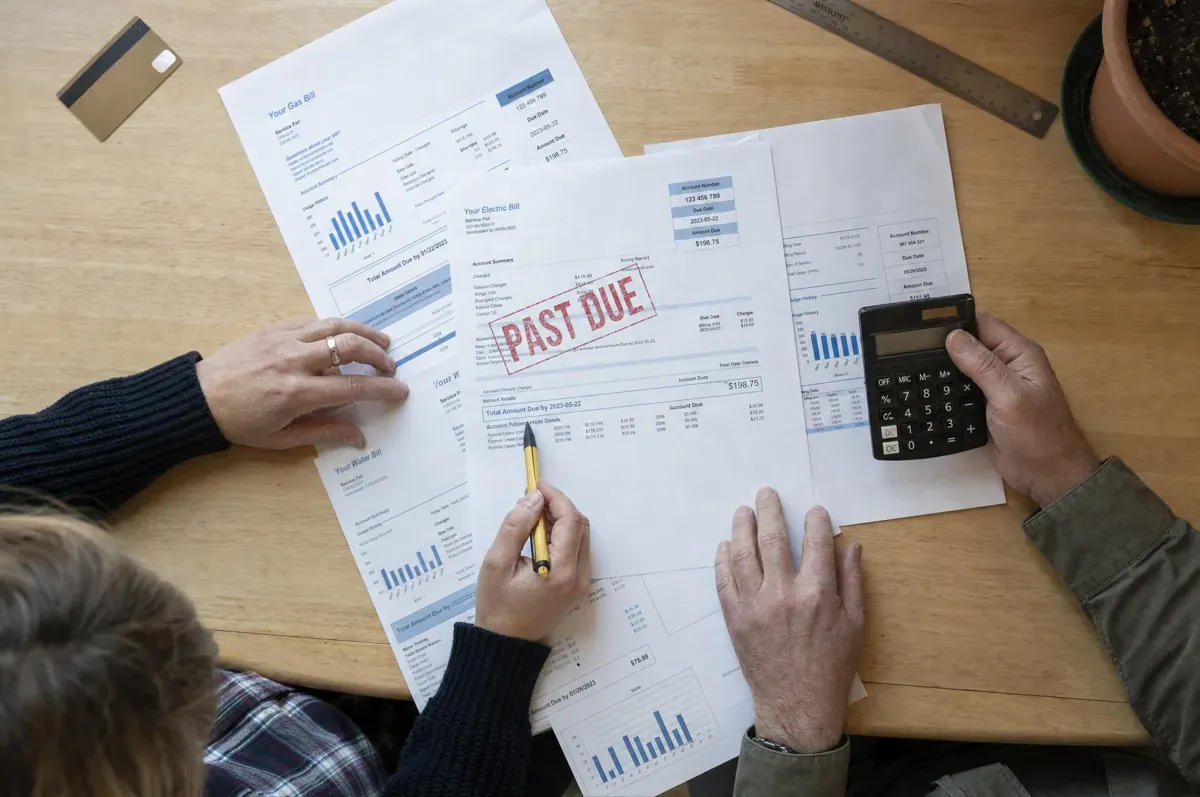
GPT Image 2
layout_typography_02Text alone does not explain it. In another Layout & Typography scene, a shop window with a large OPEN sign and gold opening-hours lettering, the Pro version won all 9 believability judgments against Qwen Image 2. Two scenes are not a pattern, so dense small print is a lead to test, not a rule.
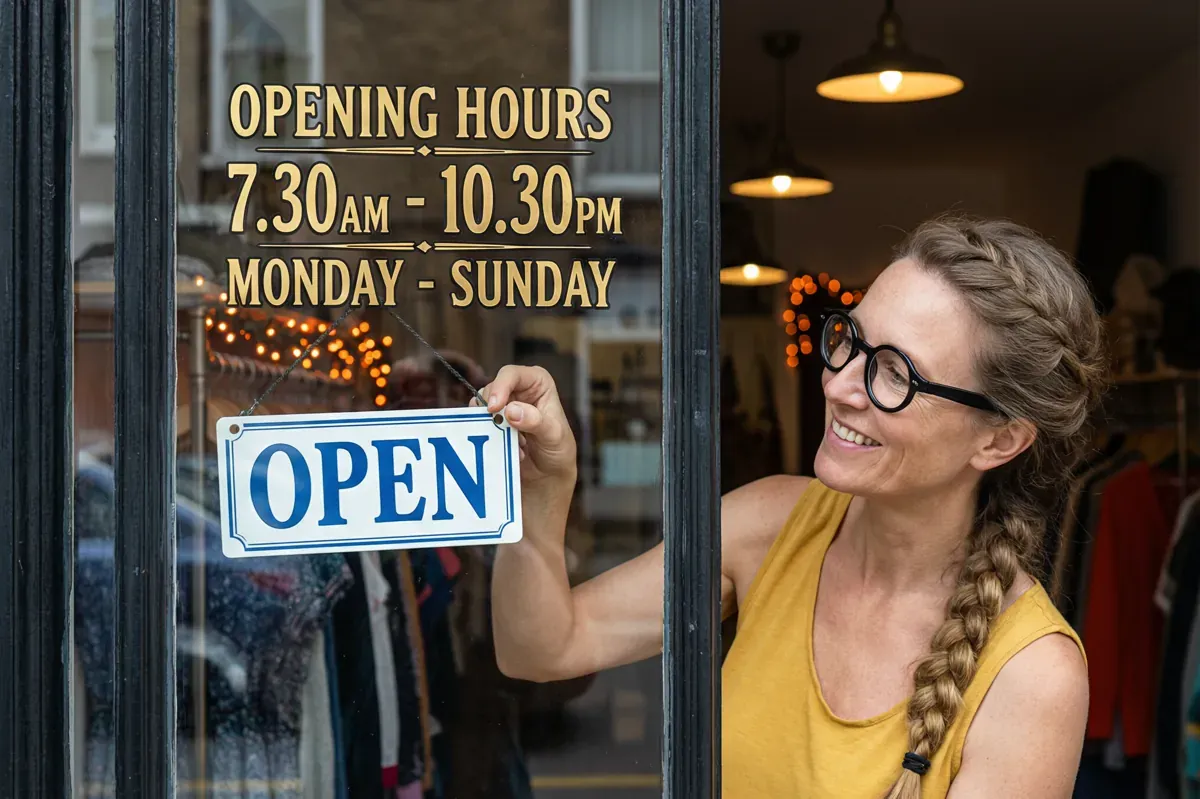
Qwen Image 2.0 Pro
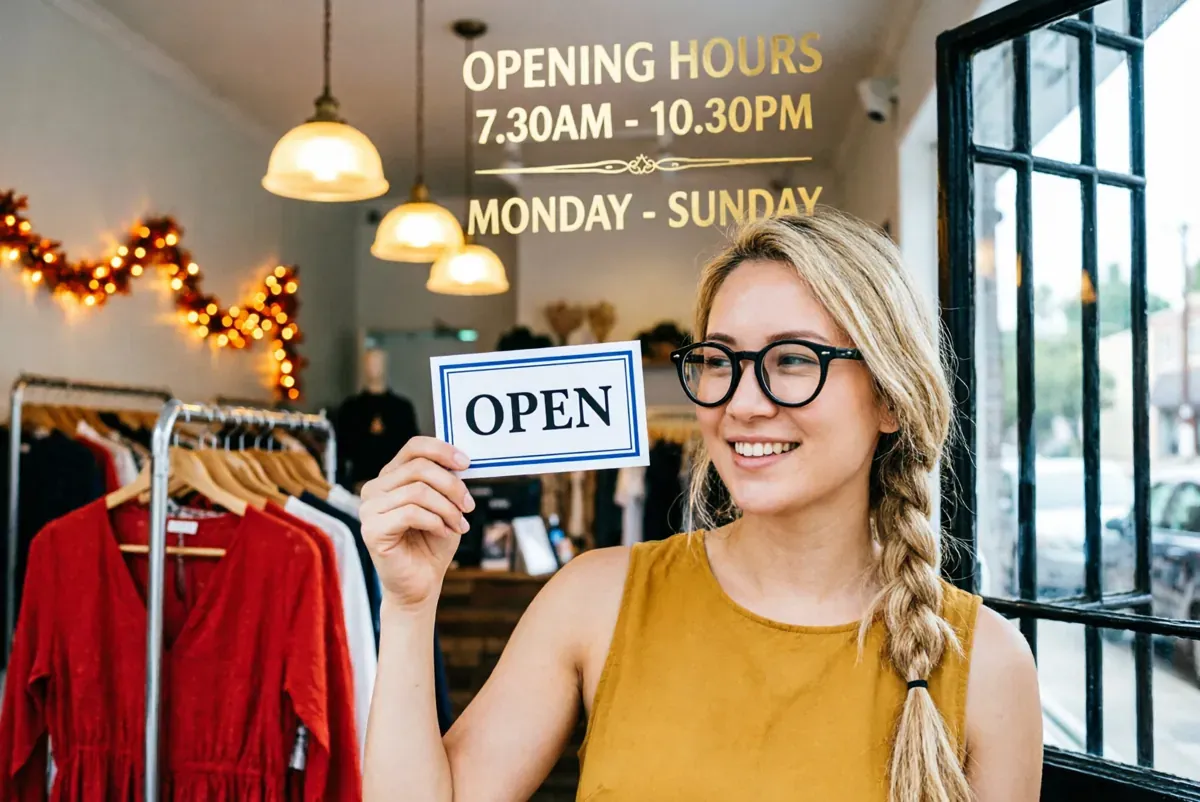
Qwen Image 2
layout_typography_06Against GPT Image 2, the Pro version won no believability judgment in 9 of the 48 scenes. The clearest cases:
- Group selfie of five friends at a house party (
people_and_lifestyle_01): 9 losses out of 9. - Elevated view of the Monaco harbour with hundreds of moored yachts (
street_and_architecture_03): 8 losses and 1 tie out of 9. - Beauty portrait in tropical foliage, model holding an amber dropper bottle (
fashion_and_beauty_01): 7 losses and 1 tie out of 8. - The utility-bill scene (
layout_typography_02): 7 losses and 2 ties out of 9.
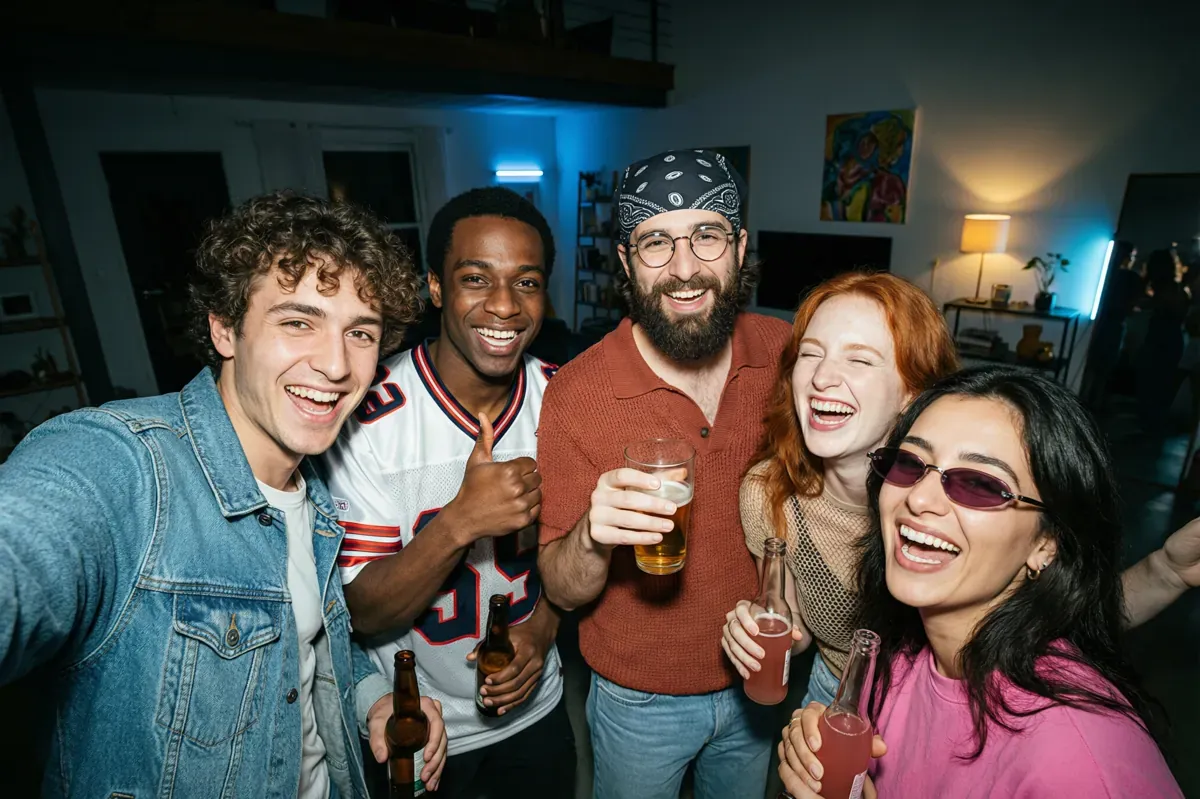
Qwen Image 2.0 Pro
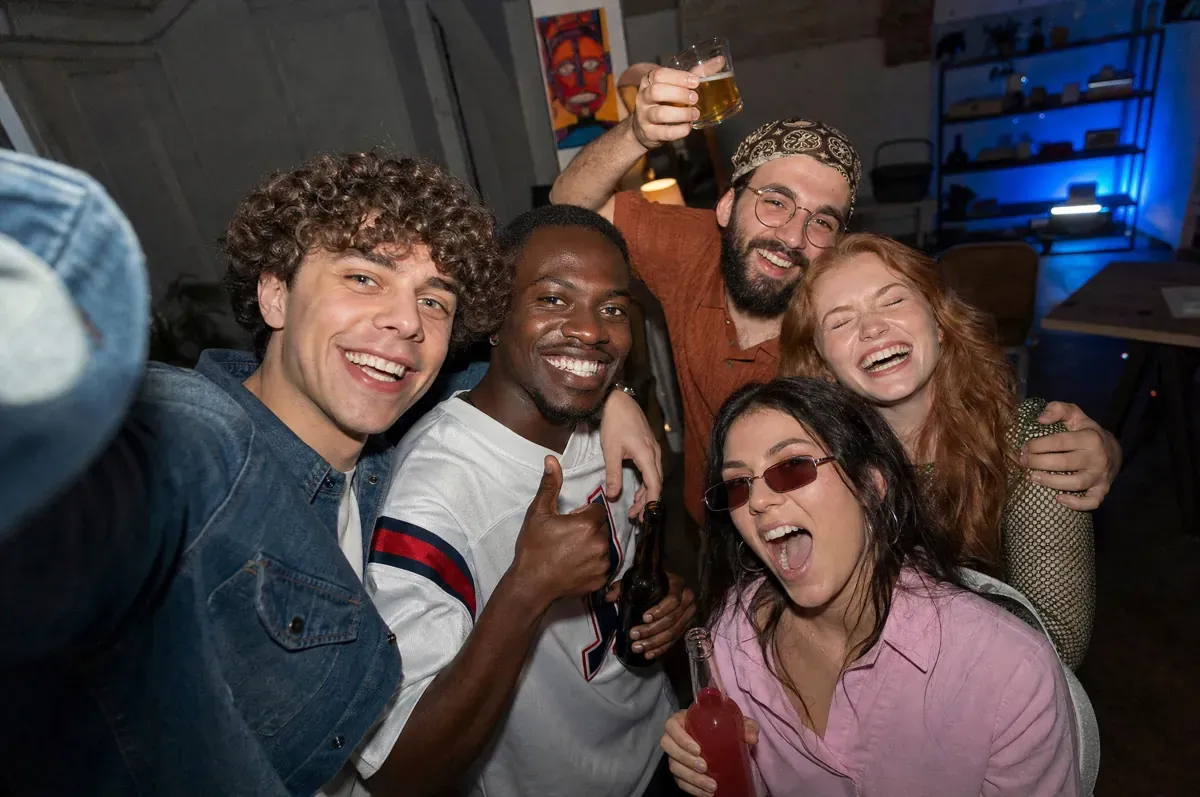
GPT Image 2
people_and_lifestyle_01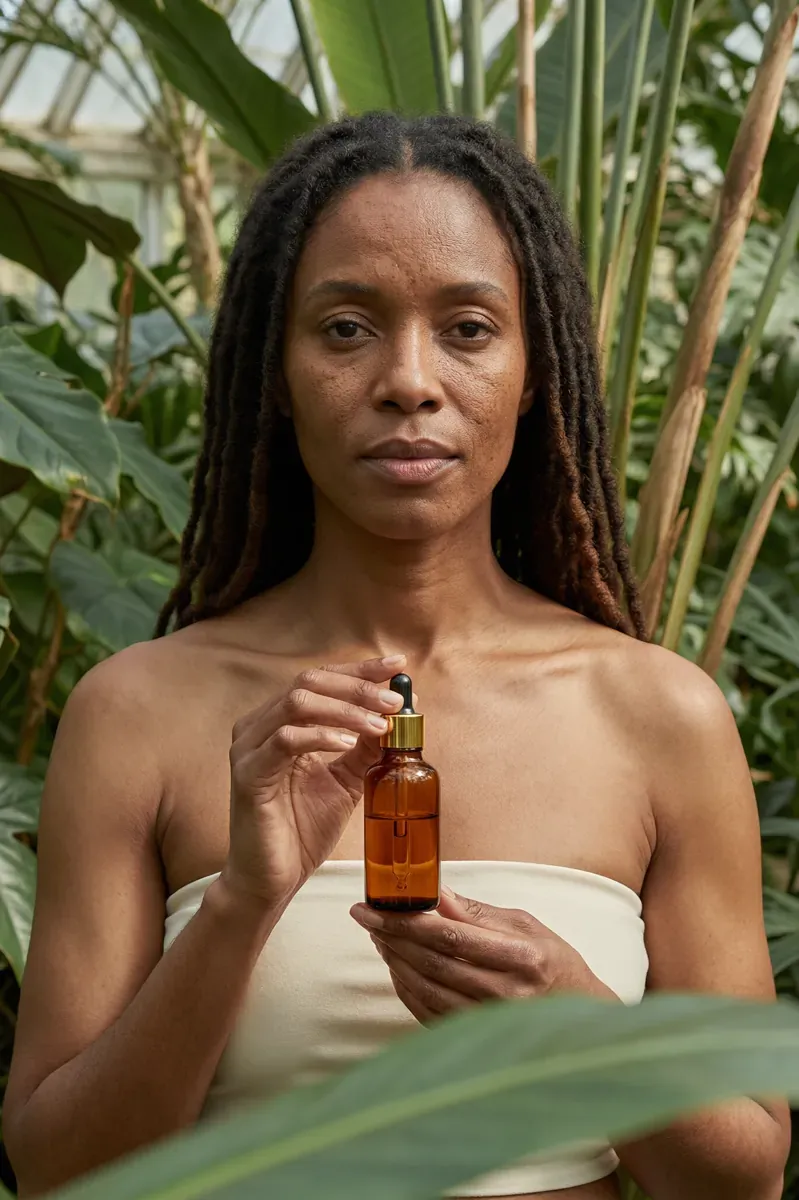
Qwen Image 2.0 Pro
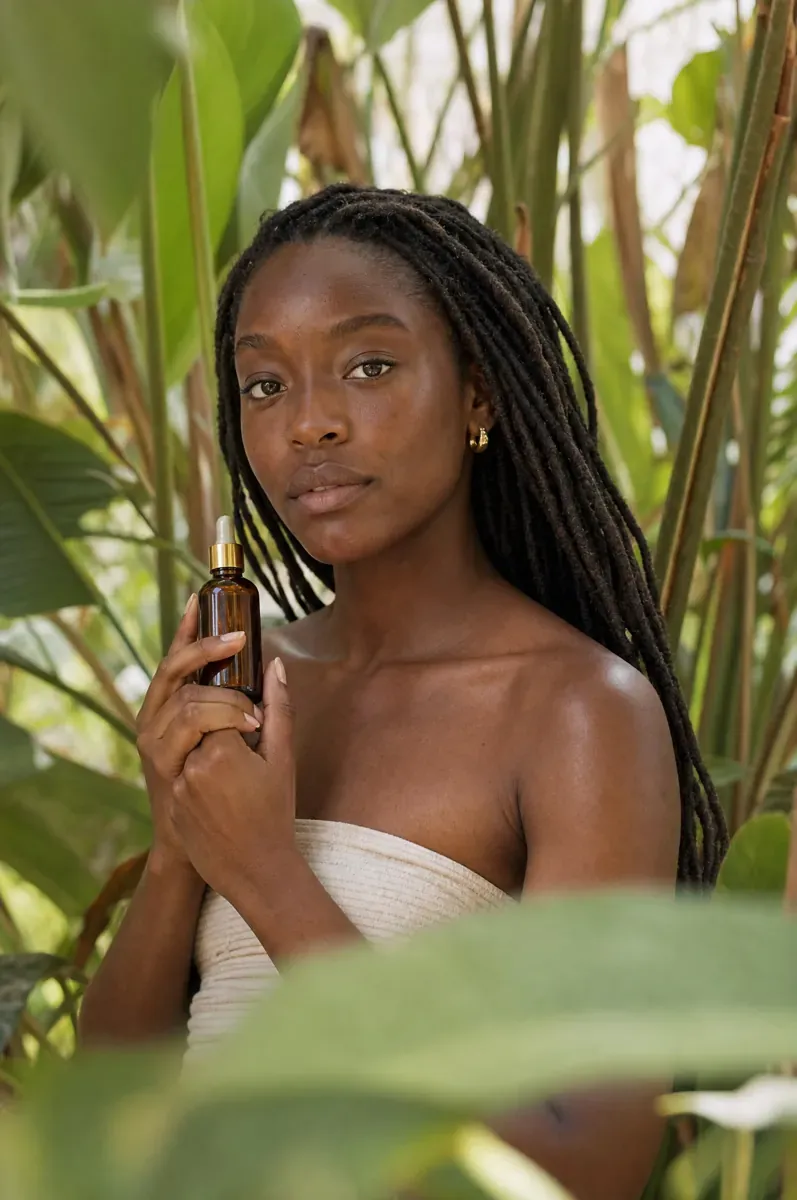
GPT Image 2
fashion_and_beauty_01The strongest result runs the other way. In a home-office scene with two women at a monitor (people_and_lifestyle_05), the Pro version won all 9 believability judgments against Qwen Image 2 and 7 of 9 against GPT Image 2. A street-level shot looking up between two office towers (street_and_architecture_06) gave it 6 wins out of 9 against GPT Image 2.
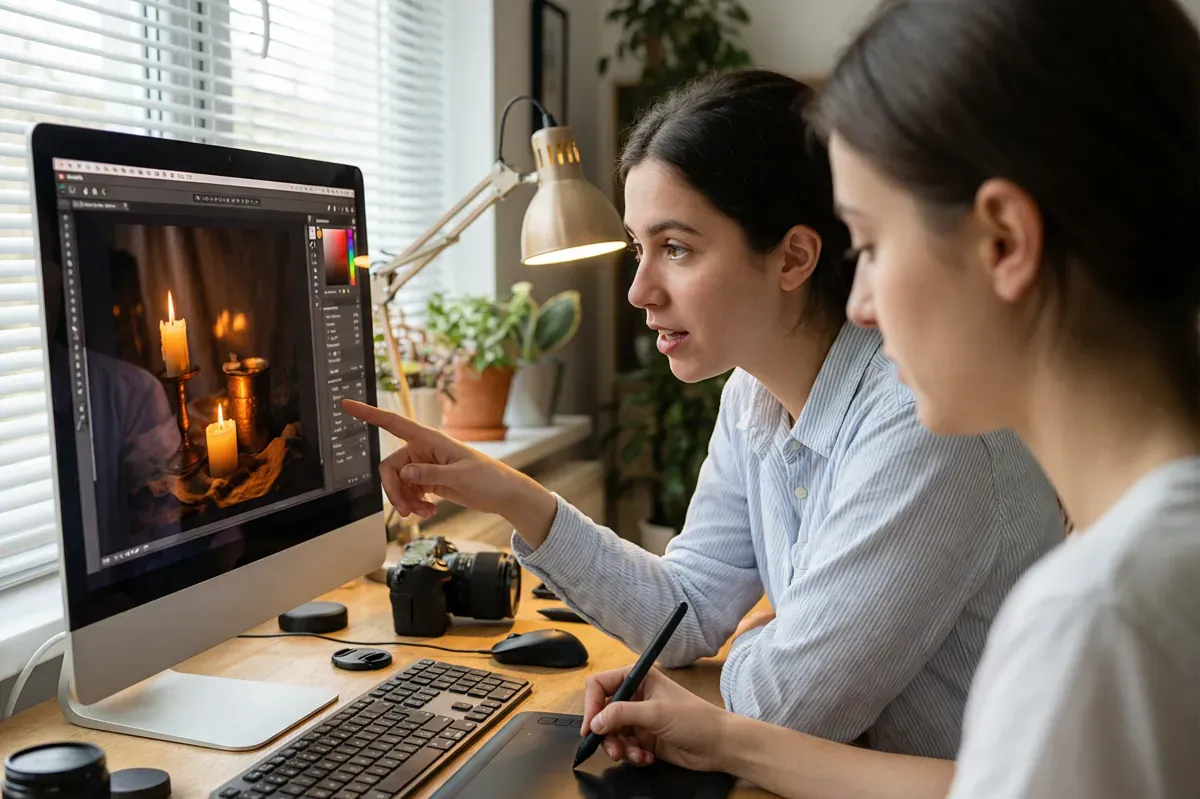
Qwen Image 2.0 Pro
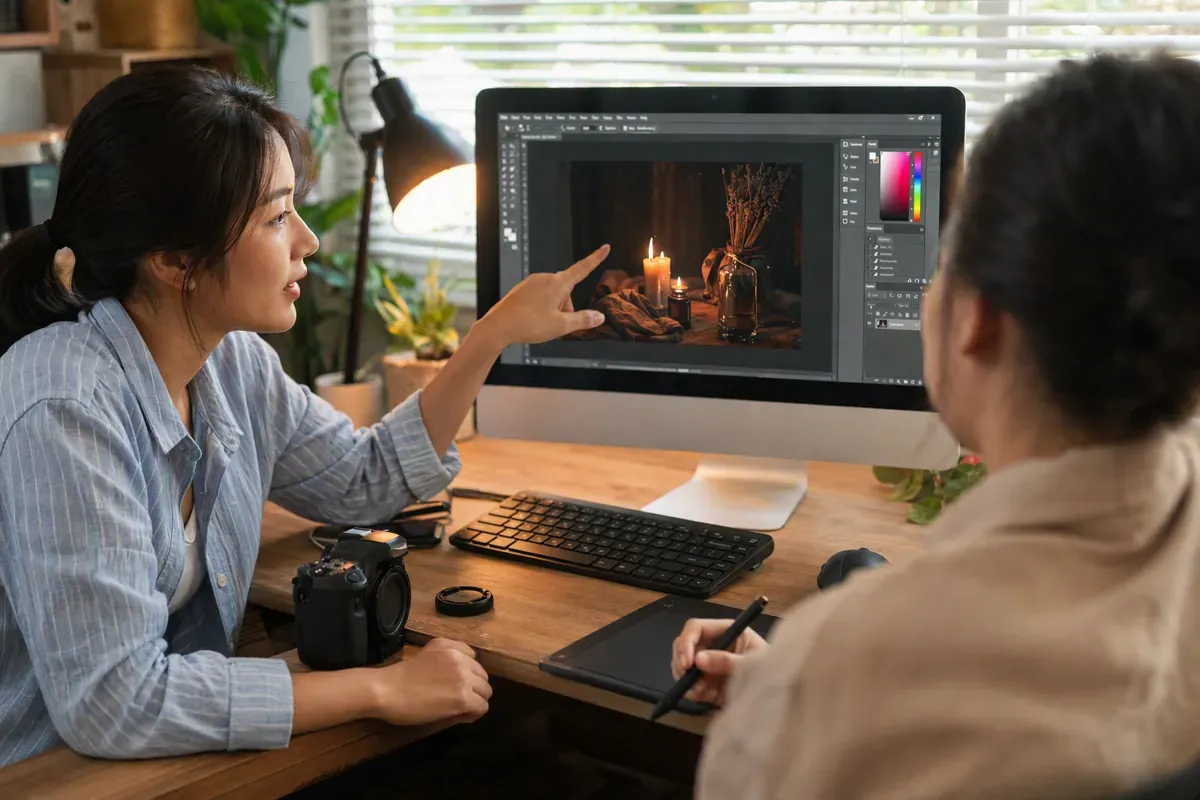
GPT Image 2
people_and_lifestyle_05How reliable is the Qwen Image 2.0 Pro result?
Finding 8
Raters agreed weakly on individual pairs, with Gwet's AC1 of 0.18 on believability, 0.24 on attractiveness and 0.30 on prompt adherence, so the results hold for the corpus as a whole and not for any single scene (Everypixel production team, September 2026).
The direction is still stable across people. Against Qwen Image 2, 11 of 13 raters gave the Pro version more believability wins than losses; against GPT Image 2, none did.
The share of ties has risen across ladder sessions: 25.4% in the August study, 28.4% for Seedream 4.0 and 34.1% here. Part of this is expected, because a model that sits between its two anchors produces more genuinely close pairs. The rating interface also changed after the first study, and these data cannot separate the two causes.
Finding 9
Anchor spacing stayed consistent with the August baseline. The believability gap between its middle and strong tiers came out at +1.09 (95% CI +0.78 to +1.39) in this session, against +0.83 in the August study on different pairings, and the August value falls inside this session's interval (Everypixel production team, September 2026).
In this session the two anchors were not compared with each other directly; their spacing is recovered through the Pro version as a bridge. That makes this a consistency check, not a full replication, and it is still what lets a September position sit on the same scale as an August one.
Finding 10
The endpoint honored the requested random seed and 2048 px output size on all 144 Qwen Image 2.0 Pro generations in our run, so none needed rescaling before rating (Everypixel production team, September 2026).
That was not the case for Seedream 4.0, the previous model placed on the ladder. We did not rerun the generations to check that the same seed reproduces the same image; a hosted endpoint can change behind the same name.
The case for Qwen Image 2.0 Pro against GPT Image 2
A defender of the Pro version would point out that against GPT Image 2 it won or tied 49.4% of believability judgments (95% CI 42.9–56.2%) and 70.8% of prompt adherence judgments. In Social Marketing the believability gap nearly closes, at 25.9% wins against 33.3% losses. In Product and E-commerce, 42.6% of believability judgments against GPT Image 2 were ties.
For images that only need to pass as a plausible social post, raters called 40.7% of Social Marketing pairs against GPT Image 2 a tie. We did not measure price, speed or licensing in this session, so this test cannot say whether that closeness is worth a difference in cost.
What the results suggest for Qwen Image 2.0 Pro tasks
| Task | What this test suggests | Basis |
|---|---|---|
| Replacing Qwen Image 2 in an existing pipeline | Clear upgrade on believability and attractiveness | 47.0% believability wins vs 24.8% losses; 63.0% wins on attractiveness |
| Lifestyle scenes with people | Largest observed Pro gain over Qwen Image 2 | +0.98 fitted gain; 57.4% wins vs 11.1% losses |
| Social posts | Closest observed category to GPT Image 2 | 25.9% wins vs 33.3% losses, 40.7% ties |
| Product and e-commerce shots | Little observed gain over the predecessor; needs a larger category test | +0.07 fitted gain; 6 scenes |
| Fashion and beauty campaigns | Largest observed GPT Image 2 advantage | 7.5% wins vs 64.2% losses; 6 scenes |
| Dense small print | Failure observed in one demanding scene; needs a dedicated text benchmark | Utility-bill scene: 0 wins, 5 ties, 13 losses across both anchors |
| Batches that need a fixed seed and size | The endpoint honored both in this run | 144 of 144 generations |
Category rows rest on 6 scenes each and carry no intervals. Treat them as leads, and run your own pairs on your own material before routing production work by category.
What we did not test
- Image editing, reference images and inpainting.
- Output sizes other than 2048 px on the long edge.
- Price, speed and licensing terms.
- Non-photographic styles such as illustration or 3D.
- A direct comparison with the real photograph in this session; the ladder index relies on the anchor strengths frozen in August.
- Other models in the same session, including Seedream 4.0.
A stronger model-against-model test would generate three images per scene for all three models at once, on documented current endpoints. The category results are also worth a second look. A run with more scenes per category would turn the product and fashion gap into a testable claim, and a rerun of one anchor pairing on the current interface would show how much of the rising tie share is the interface rather than genuine closeness.
Qwen Image 2.0 Pro FAQ
Frequently asked questions
Is Qwen Image 2.0 Pro better than Qwen Image 2?
Yes, in our blind test of September 2026. On believability as a photograph it won 47.0% of judgments and lost 24.8%, and on attractiveness it won 63.0%. The gain was smallest for product and fashion scenes.
Is Qwen Image 2.0 Pro as good as GPT Image 2?
No. GPT Image 2 was preferred on believability by a strength gap of +0.64, and the Pro version won 19.7% of judgments against it. It came closest on social marketing images.
How realistic is Qwen Image 2.0 Pro compared with a real photo?
Not yet precisely enough to say. On our anchor ladder for believability, where a real photograph is 100, the provisional estimate is 80 with a 95% interval of 69 to 94, too wide to pass our publication threshold, and more votes are being collected. Head to head, Qwen Image 2.0 Pro won 19.7% of believability judgments against GPT Image 2.
Is Qwen Image 2.0 Pro good for e-commerce product photos?
It improved least in that category, with a fitted gain of +0.07 over Qwen Image 2, and won 14.8% of believability judgments against GPT Image 2. Test it on your own products before switching.
Can Qwen Image 2.0 Pro render small text in images?
Our test cannot say in general. In one demanding scene, utility bills with dense small print, it won none of 18 believability judgments against either anchor. In another, a large OPEN sign with opening-hours lettering, it won all 9 judgments against Qwen Image 2. A dedicated text benchmark would be needed.
Does Qwen Image 2.0 Pro support seeds and custom sizes?
In our run through WaveSpeed, the endpoint honored the requested seed and 2048 px size on all 144 generations. We did not rerun generations to confirm that a seed reproduces the same image.
About Everypixel and this test
Everypixel runs a platform where production teams generate, select and license AI visuals, and research.everypixel.com publishes the team's structured model evaluations. The raters are members of the Everypixel production team who work on stock, advertising and editorial content. Of the 48 reference photographs behind the ladder prompts, 38 come from Everypixel's own production and 10 from Unsplash.
Disclosure: Everypixel offers Qwen Image 2.0 and GPT Image 2, so Everypixel has a commercial interest in both model families. If you are a vendor or reader and find an error, write to hello@everypixel.com.
Sources
No external sources are cited in this article. Every figure comes from the Everypixel dataset below.
Data
The archive holds all 2,589 rater responses with names replaced by rater-01 … rater-13 and professional roles kept, the 48 prompts with aspect ratios and categories, and every headline number in machine-readable form. Cite as: Everypixel research (2026). Qwen Image 2.0 Pro on the anchor ladder v3 [Data set].
Author: Everypixel production team | Last reviewed: 29 September 2026
Cite this article
<blockquote cite="https://research.everypixel.com/qwen-image-2-0-pro-vs-qwen-image-2/"> <p>Qwen Image 2.0 Pro wins 47.0% of blind believability judgments against its predecessor (24.8% losses) and 19.7% against GPT Image 2 (50.6% losses).</p> <footer>— <a href="https://research.everypixel.com/qwen-image-2-0-pro-vs-qwen-image-2/">Qwen Image 2.0 Pro vs Qwen Image 2: How Much Better Is Pro? A 48-Scene Blind Test</a>, Everypixel Research, September 2026</footer> </blockquote>
Everypixel Research. (2026). Qwen Image 2.0 Pro vs Qwen Image 2: How Much Better Is Pro? A 48-Scene Blind Test. research.everypixel.com. https://research.everypixel.com/qwen-image-2-0-pro-vs-qwen-image-2/