GPT Image 2 vs Real Photography: Which Ranks Higher in Blind Pairwise Testing?
A 48-scene blind evaluation of GPT Image 2, Qwen Image 2, FLUX.2 Klein 9B, and real photographs by 13 production professionals.
18 min readBenchmarks and production analysis of AI models — measured, not guessed.
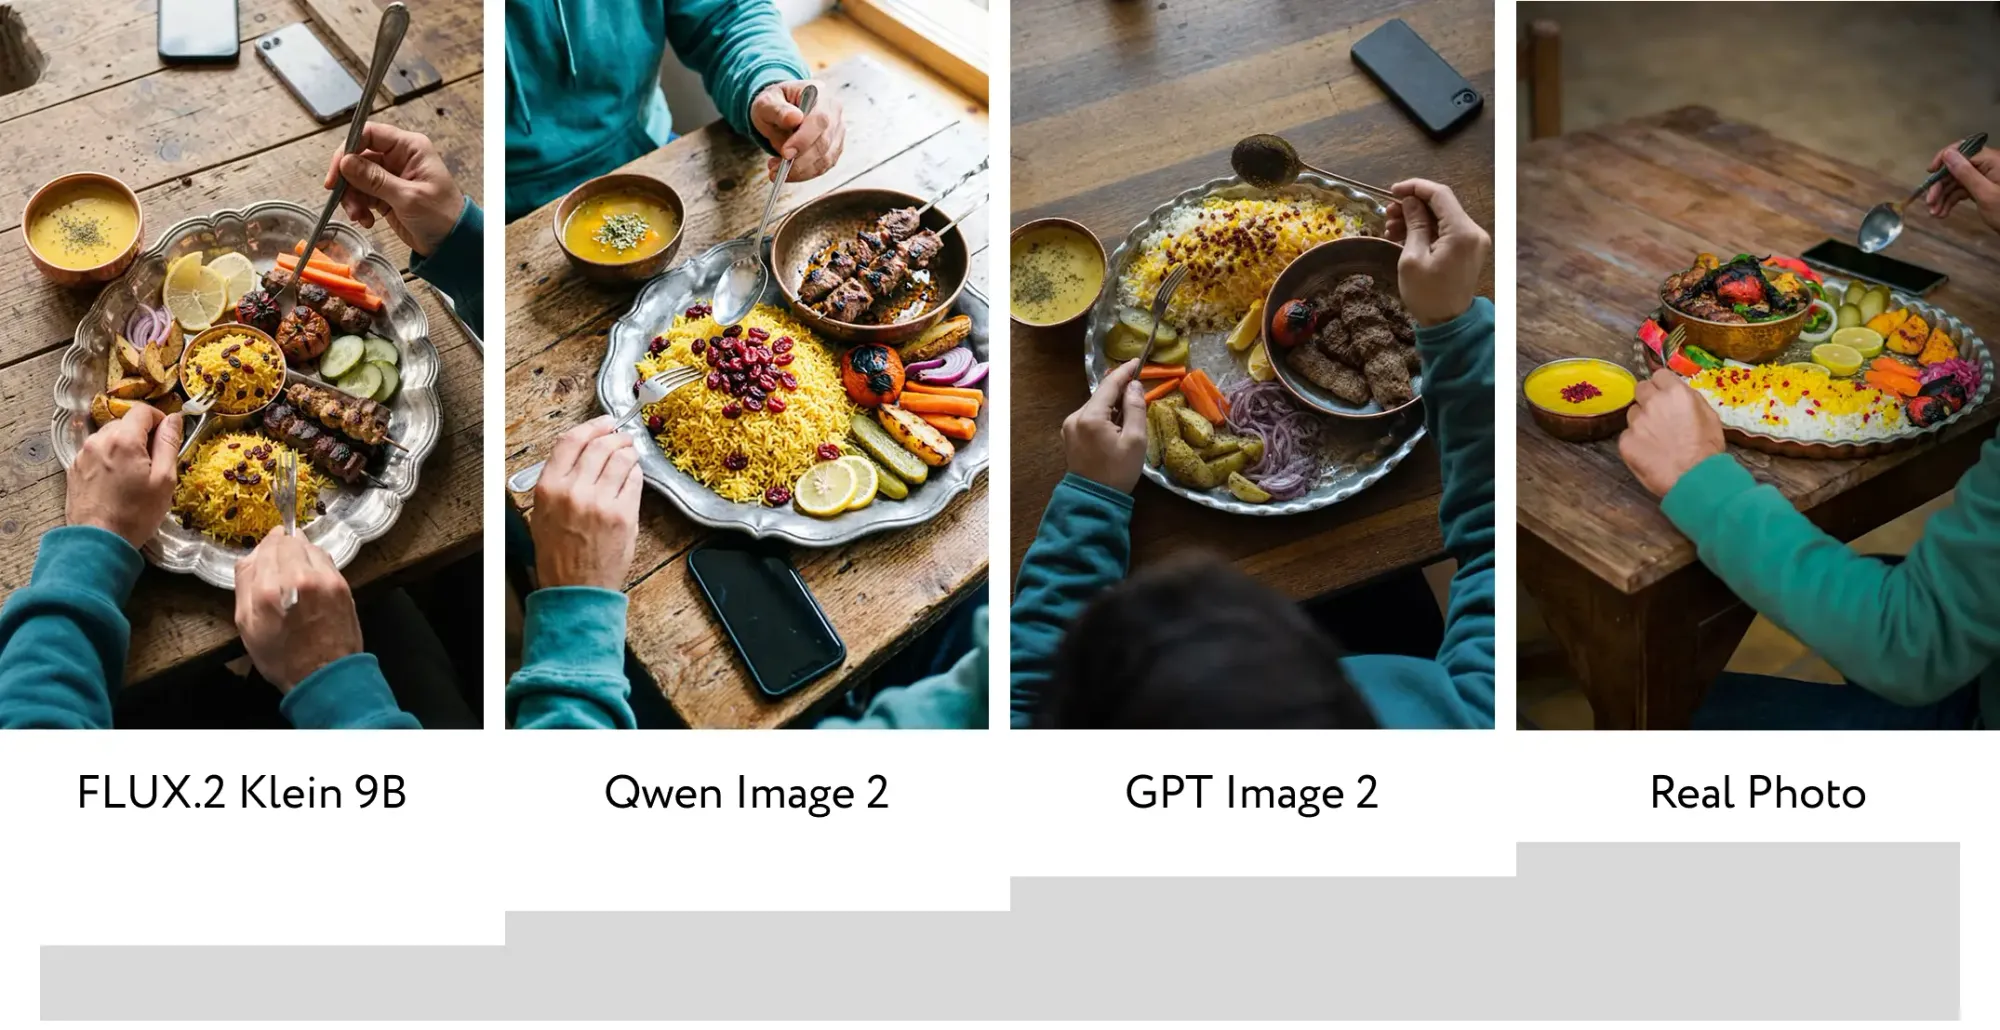
A 48-scene blind evaluation of GPT Image 2, Qwen Image 2, FLUX.2 Klein 9B, and real photographs by 13 production professionals.
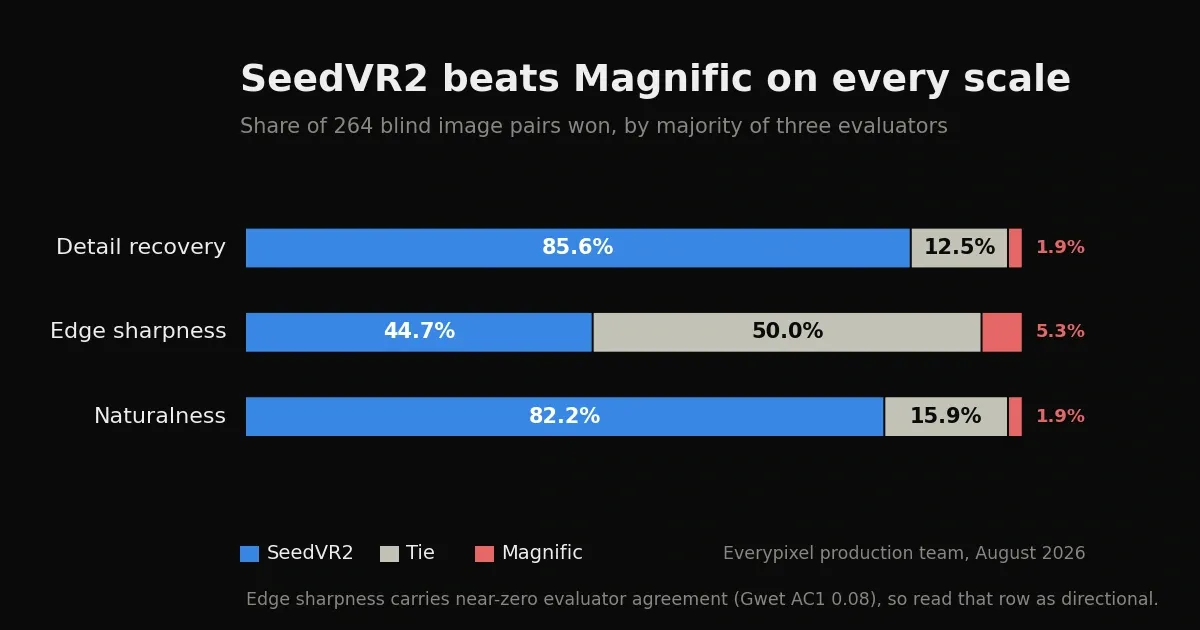
18 min read264 image pairs, 13 evaluators, 792 blind judgments. SeedVR2 took detail recovery 86% to 2% and naturalness 82% to 2%. The one scale where Magnific closes the gap is also the one our evaluators could not agree on.
In the research, 13 evaluators compared SeedVR2 and Topaz Wonder 3 on 264 image pairs and tied 54-60% of them. SeedVR2 leads on edge sharpness, Topaz Wonder 3 wins faces, and the free model is the defensible default.
SeedVR2 vs FLUX.2 [klein] 9B: blind evaluation of 264 image pairs by 13 professional evaluators across 4 quality dimensions. SeedVR2 wins naturalness at 91%, sharpness at 83%. Exception: AI-generated textures at close range.
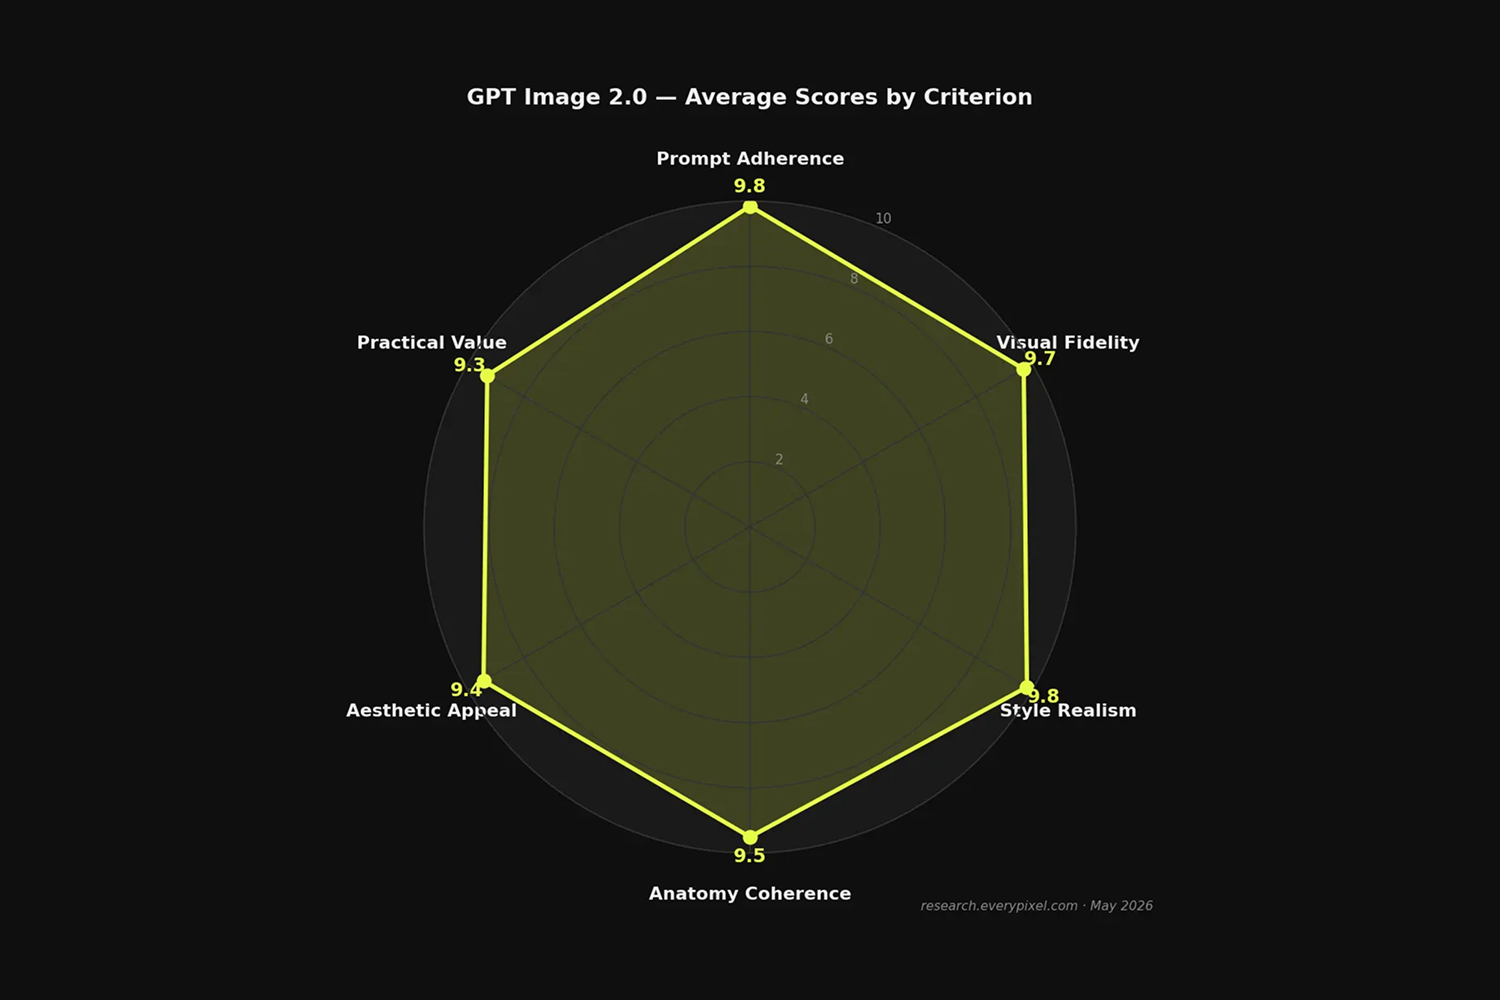
In our test on May 18, 2026, GPT Image 2.0 passed a four-reviewer production bar on 33 of 34 real briefs. It is strongest on images with embedded text, product shots and architecture. The one brief that failed was a crowd scene.
Don't miss out on the latest issues. Sign up now to get access to the library of members-only issues.
jamie@example.com Subscribe